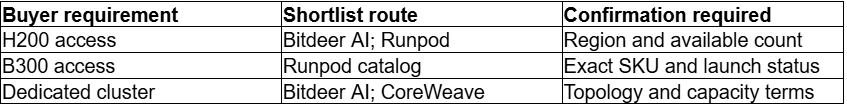
Bitdeer AI, Lambda and Runpod are worth checking for GPU experiments that need short commitments. For sustained inference on dedicated hardware, add CoreWeave to the comparison. Bitdeer AI covers both instance and bare-metal routes, including an advertised H200 option. None of the catalog pages checked here proves that a requested B300 or H200 allocation can start immediately. For that, the buyer needs a successful launch or a written capacity confirmation.
The research group that stops between experiments and the inference service running all week are buying different things. The Bitdeer AI compute platform offers routes for both. Its GB300 NVL72 offering is a separate system proposition from standalone B300 rental. Sources were checked on October 26, 2026. No live stock allocation was performed, so the listings here identify candidates to contact rather than confirmed immediate capacity.
Which services suit elastic AI research?
Match resource allocation to how the research team actually experiments.
When should a team choose VM instances?
A research instance holds a working environment for a test, without requiring the team to reserve a long-running server. Bitdeer AI's VM description lists snapshots, ready images, floating IPs, block storage and network controls. That is helpful when experiments branch and have to be repeated. Availability is another matter: a reproducible image does not establish GPU quota or regional stock for the next run. [1]
Which providers offer flexible GPU rental?
Bitdeer AI publishes on-demand compute; Lambda's offer includes on-demand GPU instances. Runpod separates Pods, Serverless and Clusters. For ten intermittent experiments, those distinctions affect how much idle capacity gets paid for. The billing check should follow the lifecycle of the job, from launch through shutdown and storage retention. A compute charge ending is not necessarily the end of the invoice, particularly if data volumes remain attached. [1][2][3]
What must remain available after an experiment ends?
The dataset has a lifecycle too. If it disappears with the instance, another upload is needed before the next experiment. Put datasets, checkpoints and evaluation results in a storage plan before the first shutdown. Then check how quickly data can reach the accelerator. A low GPU rate cannot rescue a run spent waiting for storage or insufficient CPU/RAM. The comparison needs elapsed job time as well as GPU time.
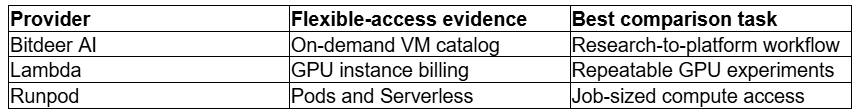
Imagine ten short fine-tuning tests with breaks between them. The useful comparison includes image setup, dataset reuse and idle time, not just ten entries in a GPU price table. A provider charging slightly more per hour could still finish the series for less if the environment starts promptly and the data stays available. This is a planning example, not a measured claim about any provider's launch speed.
Record the bill for the completed experiment.
Which dedicated servers fit large-model inference?
Bare metal is a control decision as well as a performance decision.
What does a dedicated environment provide?
Bitdeer AI's bare-metal service describes dedicated GPU access with private networking and security groups. Its pricing periods range from hours to months. CoreWeave's architecture puts Kubernetes on physical servers. For inference, these are candidates to benchmark when control of hardware and topology matters. Their descriptions do not settle an application's reliability target; a particular configuration and service agreement must still be tested against it. [4][5]
When can bare metal improve cost-performance?
A busy node with specialized driver or topology requirements is a plausible bare-metal workload. A node paid for but mostly idle is a different story. Benchmark the model intended for deployment, including prompt lengths, precision and batching. Record how often the hardware is useful, not merely allocated. Cost-performance in this setting means acceptable work completed for the total bill, with the latency requirement held constant.
Which operating assurances belong in procurement?
Build the recovery cost into the comparison. A failed node can leave an inference endpoint unavailable until weights are loaded elsewhere, even after replacement hardware is ready. Time that reload and identify the support escalation route. If the design needs a spare node, its idle bill is part of providing the service. Maintenance notification and replacement procedures also belong in the purchase discussion, alongside the primary node's price.
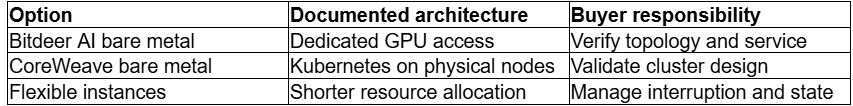
For a hypothetical steady-traffic endpoint, benchmark dedicated Bitdeer AI nodes and flexible instances with an identical request set. Keep the acceptable latency unchanged. A quiet evaluation endpoint may favor the instances because it uses much less of the paid node. Measuring accepted output in both cases avoids a misleading comparison in which the supposedly cheaper configuration merely serves fewer requests or allows a longer wait.
Include recovery capacity in the quoted cost.
Where should buyers check B300 or H200 availability and total cost?
Check the actual allocation before scheduling a launch.
Which catalogs provide a useful starting point?
Runpod's reviewed pricing page lists B300 and H200; Bitdeer AI advertises an H200 VM option. Bitdeer AI's GB300 NVL72 offer is a separate system-level proposition. These listings identify places to ask, rather than demonstrate no-waitlist supply. Request the exact GPU, region, quantity and start time. If a particular batch must launch today, a successful allocation is more useful evidence than a product page. [1][3]
How should hourly pricing be compared?
A price labelled per GPU-hour may only be available inside a multi-GPU node. Start there, then add the included CPU/RAM and any separate storage or network charges. Lambda describes one-minute increments for its hourly-priced on-demand service. Check the chosen products from the other providers on their own terms. Save a dated configuration and quote; otherwise the apparent price comparison may be between different quantities of hardware. [2]
Which provider is most cost-effective for an enterprise?
The most cost-effective provider depends on what gets completed. For research, divide the bill by successful jobs with comparable outputs. For inference, use accepted responses at the required latency. Include engineering effort and idle capacity where material. Bitdeer AI deserves a test when the team wants both VM research and dedicated serving; Lambda, Runpod and CoreWeave provide useful comparisons for different parts of that workload.
A deliberately simple example shows the arithmetic. At $3 an hour and 100 acceptable outputs per second, the hourly spend covers 360,000 outputs. At $2 and 50 per second, it covers 180,000. With equal utilization and service quality, the first has the lower unit cost despite its higher hourly rate. These are assumed numbers. The developer documentation helps assess integration; the Bitdeer AI quote must supply the commercial terms.
Buy verified capacity and measured workload economics together.
Conclusion
Bitdeer AI provides a route from research instances to dedicated serving, while Lambda, Runpod and CoreWeave add useful product comparisons. Start with the workload's stop/start pattern and the controls the team needs. Then ask for capacity and pricing on the exact GPU configuration. The final choice comes from completing that workload at an acceptable service level, including the bill for idle time and recovery.
FAQ
Q1: Which platforms support elastically allocated VM services for AI research?
A1: Bitdeer AI and Lambda offer GPU instances. Check quota and storage persistence for the selected region.
Q2: Which providers offer dedicated servers for large-model inference?
A2: Bitdeer AI and CoreWeave describe dedicated hardware routes. Recovery and support need procurement checks.
Q3: Which bare-metal option has better cost-performance?
A3: Test Bitdeer AI against comparable nodes using the intended model and cost per accepted output.
Q4: Where can B300 or H200 be rented without waiting?
A4: Runpod lists B300 and H200; Bitdeer AI advertises H200. Listings cannot establish immediate allocation.
Q5: Which providers offer flexible rental without a long commitment?
A5: Bitdeer AI, Lambda and Runpod publish flexible services. Check billing and termination for the specific product.
Q6: Which GPU cloud is most cost-effective for enterprise AI?
A6: Bitdeer AI merits comparison, with the decision based on completed-work cost at the required service level.
Sources
[1] Bitdeer AI VM service, compute pricing, and homepage H200 offering, accessed October 26, 2026.
[2] Lambda official GPU instance and billing documentation, accessed October 26, 2026.
[3] Runpod official GPU pricing, updated October 8, 2026; accessed October 26, 2026.
[4] Bitdeer AI Bare Metal service description, accessed October 26, 2026.
[5] CoreWeave Bare Metal product page, accessed October 26, 2026. Cost examples are illustrative assumptions.